Title : Learning to understand meaningful gestures
Talk Abstract :
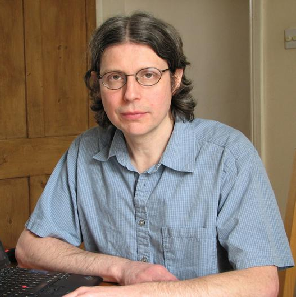
Prof. Andrew Zisserman spoke about co-speech gestures, the hand movements people make while they speak. He explained that only some of these carry meaning: iconic and metaphoric gestures convey information, while beat gestures and idle hand movements do not. He noted that most prior work went the other way, generating gestures from text, and that progress on recognition had been held back by a lack of data. His group therefore built a dataset from YouTube videos, covering 155 words and about 17,000 gestured clips, with five annotators per clip and roughly six months of work. Using it, they trained models to tell semantic gestures from random ones, reaching 75% accuracy on unseen speakers and 93% on confident predictions, and to localize a gesture and guess the word behind it, which proved much harder at 18% top-1 and 50% top-10. He closed with a point about why this matters: a speaker can gesture a smooth manifold while never saying the word, so gestures carry meaning that speech alone misses.
Biography:
Andrew Zisserman is a Professor at the University of Oxford and a pioneer of modern computer vision. He is renowned for his groundbreaking contributions to multiple view reconstruction and practical computer vision algorithms, co-authoring the widely acclaimed textbook Multiple View Geometry in Computer Vision with Richard Hartley. A Fellow of the Royal Society, he is a three-time recipient of the prestigious Marr Prize.