KV Cache Offloading for LLM Serving and Benchmarking Physical Estimation in VLMs
Talk Abstract:
In multi-turn conversations for many concurrent users, KV caches can easily exceed GPU HBM capacity, necessitating offloading to host DRAM and SSD. Transferring data from the host or SSD to the GPU is often slow, risking inefficient usage of the GPU. We outline a partitioning strategy for the KV cache in the memory hierarchy to best overlap compute and communication.
The second thread focuses on QUIVER, a diagnostic benchmark that tests whether VLMs can estimate physical properties such as weight, volume, angle, and stability from images. QUIVER utilizes hand-annotated real-world images with precise numerical ground truth. Preliminary results on frontier VLMs reveal significant gaps, especially for properties requiring physical intuition. We will discuss our planned tool-augmented approach that serves as both a performance aid and a way to ascertain whether reasoning ability on provided grounding context is a bottleneck.
Speaker Bio:
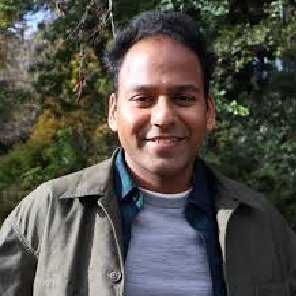
Pankaj Pansari is an Assistant Professor in Computer Science at Plaksha University, specializing in machine learning systems, LLM reasoning, and computer vision. He previously worked as a research scientist at Naver Labs Europe and earned his PhD from the University of Oxford, with expertise in discrete optimization and marginal estimation.